Entry #6: Learning Faces and Voices
Omocube can now remember people by face and by voice. This is what lets Omocube address someone by name, keep an accurate sense of who said or did what, and keep what it knows about one person from bleeding into what it knows about another.
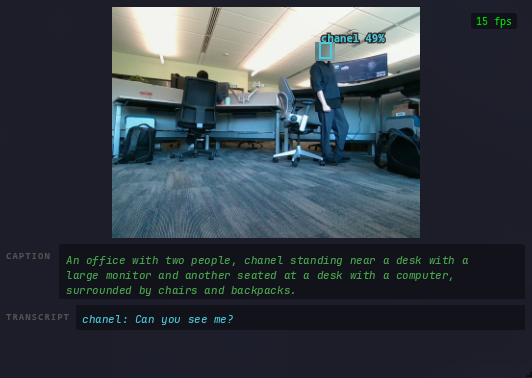
Recognition runs entirely on Omocube. Voice samples, face registers, and the names attached to them are never uploaded or matched against some larger database elsewhere. They get converted to numerical fingerprints that stay on-device.
1 — Enroll once
Face
A handful of shots at different angles and lighting
Voice
A few short recordings of them speaking naturally
2 — A fingerprint
Kept as a set of numbers used for comparison. Does not use raw photos or audio, and never leaves Omocube.
3 — Every time it sees or hears someone
Match found
Maya
Addressed by name.
No match
someone
Treated as “someone”.